The assumption most people carry about frontier-scale open models is that running one needs a datacentre aisle, or a rack of NVIDIA hardware with a seven-figure invoice attached.
It needs one virtual machine.
On 9 August 2026, in France Central, we loaded Kimi-K3 onto a single
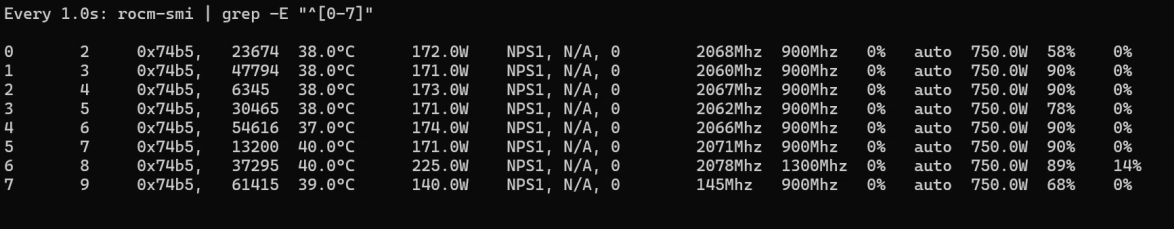
ND96is_MI300X_v5: eight AMD Instinct MI300X cards, 1,531.6 GiB of GPU memory in one box,
renting at roughly $11 an hour on spot. The model is 2,779 billion parameters. It fits, with
room left over.
Why this is worth writing down now
Twelve months ago the trade-off was simple and unsatisfying: the models you could download and own were meaningfully behind the models you could only rent through an API. That is no longer a safe assumption.
On 2 September 2026, Arena.ai's Code Arena WebDev board put Qwen3.8-Max-0902 first overall at 1,691 points. Claude Opus 5 Max was second at 1,688. Kimi-K3 Max was third at 1,674.
Two of that top three are open weight. Both of them fit on the box described in this article.
That is the part worth sitting with. The question is no longer whether an open model is good enough. It is where you would like the good model to live.
The box
ND96is_MI300X_v5, France Central, spot:
- 8 x AMD Instinct MI300X
- 8 x 196,048 MiB of HBM, so 1,531.6 GiB usable, 1,645 GB decimal
- 96 vCPUs
- Roughly 2 TB of system RAM
- 28 TB of local NVMe
- About $11 per hour on spot at the time of the session
The load, with numbers
Kimi-K3, UD-Q4_K_XL quantisation:
| measure | reading |
|---|---|
| Parameters | 2,779 billion |
| Weights on disk | 1,405 GiB |
| VRAM used | about 92% of each card |
| Free before KV cache | roughly 8% of the box |
| Model pull to RAM disk | 417 seconds |
| Pull throughput | 28.9 to 31 Gbit/s |
| Prefill | 248 tokens/sec |
| Session cost | under $30 of spot |
The download figure deserves a note of its own, because it is the part people assume will be the bottleneck. Pulling 1.4 TiB of weights from Hugging Face, across the Azure backbone, onto a RAM disk, took under seven minutes. On infrastructure like this the model transfer is not the slow part of the day.
What we are not claiming
Decode on that 9 August pin measured 14.27 tokens/sec. We are publishing it as provisional and you should read it that way. It came off a pre-merge build with unoptimised kernels, and the formal three-prompt coherence check was not run on that configuration. There is a specific reason we suspect the build rather than the hardware: the same box was faster at Q4 than at Q2, despite moving 1.75 times the bytes per token. A purely bandwidth-bound decode path would have gone the other way. That points at the dequantisation path in the build, not at the cards, and it stays provisional until we can rerun on the shipped image.
The other honest limitation is context. With weights occupying about 92% of each card, what remains for KV cache is modest. You are not serving a 200k-token context window to a room full of people on this configuration. The finding here is placement, not throughput: a model of this size fits, intact, on one rentable machine.
Both of those gaps close the next time we can get a box. Which brings us to the awkward part.
The catch is capacity, not software
The appliance supports this SKU fully. The AMD build validated 16 of 16 menu models on this hardware in August, with Secure Boot on. There is nothing outstanding on the software side.
What we cannot currently do is get a box.
ND96is_MI300X_v5 is offered in two Azure regions. Since late August we have not had a single
successful allocation in either of them, across two subscriptions, despite many attempts. Spot
allocation refuses. On-demand quota requests are declined. Every dashboard we can read,
including our own, continues to report the SKU as available and attractively priced, because
price and published eviction bands cannot see an allocator saying no.
This is what the current compute crunch looks like from ground level. The hardware is extraordinary, the software is ready, and the constraint is simply that demand for this class of silicon exceeds what exists. Nothing about that is specific to one cloud.
The only signal that told us the truth was trying, repeatedly, and recording what came back. That is now a standing job here rather than an occasional one.
What we would tell you to do about it
If you have MI300X capacity in your own subscription, you are holding something genuinely scarce, and a 2.78 trillion parameter model will fit on it today.
If you do not, the useful move is to stop shopping by specification and start shopping by what actually deploys. Our sizes and regions page lists every VM size the appliance stands behind, which regions price them, where the hardware genuinely exists, and the three we would pick. It updates daily.
The giant models wait on a box you can get. Everything smaller on that page is available now, and the appliance deploys the whole stack into your own Azure tenant, with nothing leaving your subscription.
Pick a box that starts.
Receipts: all figures from a session on ND96is_MI300X_v5 in France Central, 9 August 2026, unless otherwise dated. Kimi-K3 at UD-Q4_K_XL. VRAM readings from rocm-smi on the box. Spot pricing is a reading at the time of the session, not a quote; spot prices move. Decode is provisional pending a rerun on the shipped image. Leaderboard standings are the Arena.ai Code Arena WebDev board as published on 2 September 2026 and will have moved since.